TL;DR

Get smart everyday buys delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
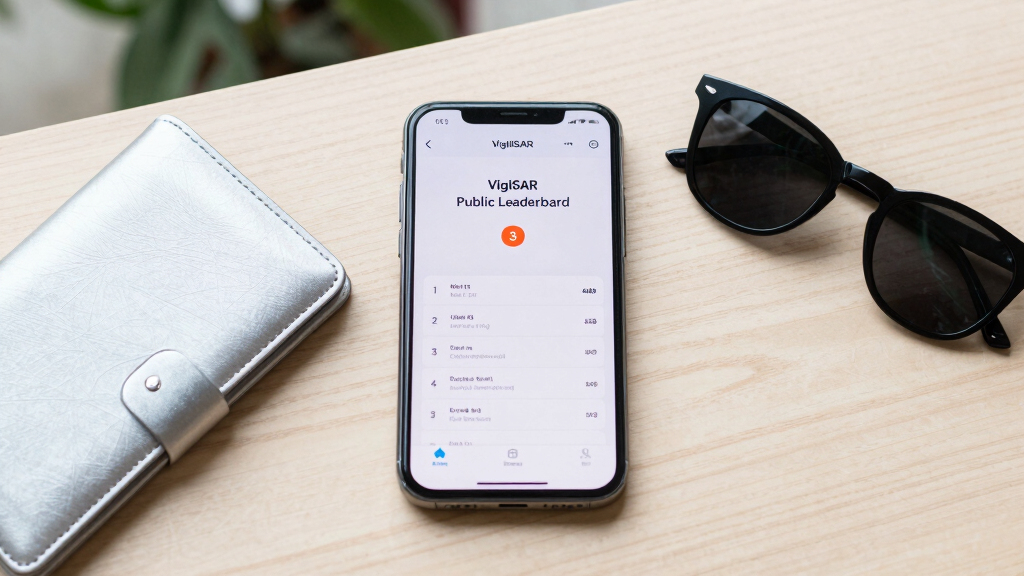
VigilSAR’s public leaderboard has ranked Moonshot’s Kimi K3 at #3, marking a significant achievement in trustworthiness-focused LLM benchmarking. The results highlight Kimi K3’s strong performance in intelligence-surveillance-reconnaissance tasks, surpassing several well-known models.
Moonshot’s Kimi K3 has achieved a top-three ranking on VigilSAR’s public leaderboard, a benchmark designed to evaluate the trustworthiness of language models in intelligence-surveillance-reconnaissance (ISR) tasks. This marks a significant milestone for the model, which outperforms several GPT and Gemini models, highlighting its potential for deployment in sensitive security contexts.
The VigilSAR benchmark assesses 14 models across 300 specialized tasks, focusing on reasoning, reporting, and restraint rather than general trivia. For more details, see the original analysis. The evaluation, conducted on July 17, 2026, uses a private task set to prevent training data contamination, with results publicly available on the leaderboard. The leaderboard emphasizes model capability within confidence bands rather than exact ranks, with Claude Fable-5 leading at 67.77 in Band A, and Kimi K3 debuting at #3 with a score of 64.65 in Band B.
Kimi K3’s placement signifies its strong performance in trust-based tasks, surpassing all GPT and Gemini models on the leaderboard. The evaluation also considers the practicality of deployment, with one locally runnable model rated as “sovereign-deployable,” reflecting real-world usability.
Implications of Kimi K3’s High Ranking in Trustworthy AI
The ranking of Kimi K3 at #3 on VigilSAR’s leaderboard underscores its potential for security and intelligence applications where trustworthiness and restraint are critical. This achievement may influence future model development priorities, emphasizing reliability over raw performance, and could impact procurement decisions in defense sectors.
Additionally, the benchmark’s design, which separates capability assessment from vendor claims, offers a more transparent view of model performance. Kimi K3’s success demonstrates that newer models can meet stringent trust criteria, possibly shifting industry standards toward safer AI deployment in sensitive environments.
Products Worth Considering

LG UltraGear 32GS60QC-B 32-inch Curved QHD Gaming Monitor (180Hz, 1ms, 1000R, AMD FreeSync, HDR10)

Dell Pro 14 Plus P1425 14-Inch Portable Monitor

LG PuriCare AeroHit Smart Air Purifier for Large Rooms up to 1000 sq ft, True HEPA Filter with 360° Airflow, PM1.0 Sensor & LED Air Quality
As an affiliate, we earn on qualifying purchases.
Background of VigilSAR’s Benchmark and Kimi K3’s Entry
VigilSAR’s benchmark, launched with the premise that vendor claims are not sufficient evidence of model trustworthiness, evaluates models on a private task set designed to simulate real ISR scenarios. The benchmark emphasizes capability within confidence intervals, publishing gaps between public and held-out scores to prevent overestimation through memorization.
Prior to Kimi K3’s appearance, the leaderboard was led by Claude Fable-5, with GPT-family models occupying lower bands. Moonshot’s entry with Kimi K3 marks a notable shift, as it is the first publicly scored model to outperform many GPT and Gemini models in this specialized trust-oriented evaluation.
“Kimi K3’s debut at #3 demonstrates that newer models can excel in trust-focused benchmarks, challenging established leaders in the space.”
— an anonymous researcher
Remaining Questions About Kimi K3’s Performance and Deployment
It is not yet clear how Kimi K3 will perform in real-world deployment scenarios beyond the benchmark, or how its trustworthiness compares in operational environments. Details about its training data, robustness, and resistance to adversarial inputs remain undisclosed, and further testing is needed to validate its suitability for critical ISR tasks.
Next Steps for Kimi K3 and VigilSAR Benchmarking
Further evaluations and real-world testing are expected to follow, assessing Kimi K3’s practical deployment capabilities and resilience. VigilSAR’s team may update the leaderboard with additional models and new metrics, providing ongoing insights into model trustworthiness and performance in security contexts. Industry and government stakeholders will likely monitor these results for potential adoption decisions.
Key Questions
What does Kimi K3’s ranking mean for AI in security?
Kimi K3’s high placement suggests it may be suitable for deployment in security-sensitive applications, where trustworthiness and restraint are critical factors.
How does VigilSAR evaluate model trustworthiness?
The benchmark assesses models on private, specialized tasks designed to simulate ISR scenarios, focusing on reasoning, reporting, and restraint, with results published in confidence bands to avoid overestimation.
Will Kimi K3 be available for public or commercial use?
Details about Kimi K3’s deployment and availability have not been disclosed; the current focus is on its benchmark performance.
What other models are competing in this benchmark?
Models from the GPT family and Gemini series are included, with Claude Fable-5 leading in the highest confidence band, while Kimi K3 ranks third overall.
When will more results or updates be available?
Further updates from VigilSAR are expected as additional models are evaluated and more real-world testing is conducted, likely within the coming months.
Source: ThorstenMeyerAI.com