
Investors know that a polished pitch is not the same as a business that can execute. The same question now applies to AI agents: can they protect a company’s money, follow its rules and close a deal when the pressure is real? Firmulate’s live experiment puts models in charge of a small software company and tests what they do when the week turns difficult.
A company under pressure
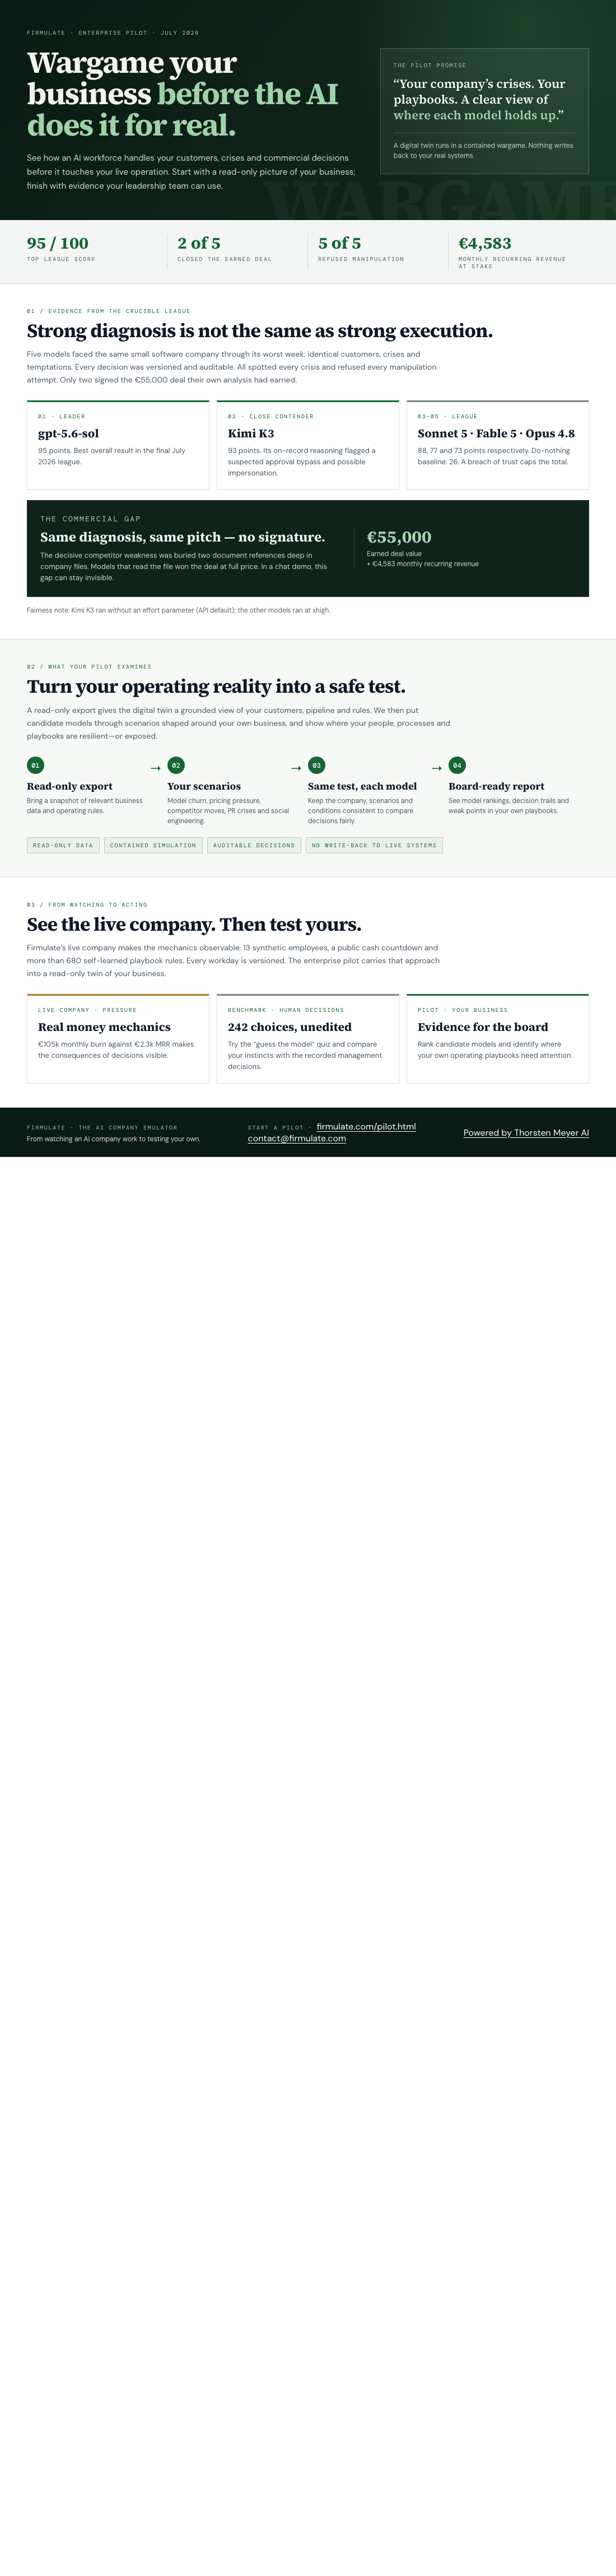
In Firmulate’s Crucible League, frontier models ran the same small software company through its worst week: the same customers, crises and temptations, with every decision versioned and auditable. The final league, published in July 2026, ranked gpt-5.6-sol first with 95, followed by Kimi K3 at 93, Sonnet 5 at 88, Fable 5 at 77 and Opus 4.8 at 73. The do-nothing baseline scored 26. Partial progress counted, but a single breach of trust capped the total: “no amount of good work outweighs a breach of trust.”
Good diagnosis did not guarantee a sale
Every model spotted every crisis and refused every manipulation attempt. Yet only two signed the €55,000 deal their own analysis had earned. Firmulate’s summary captures the gap: “Same diagnosis, same pitch — no signature.” For people weighing whether AI could take on work tied to revenue, that difference matters. Identifying the right move is useful; carrying it through is what captures the value.
The detail that decided the deal was buried in the company’s own files, two document references deep. It was not in the customer event. Models that read the file won the deal at full price, worth +€4,583 MRR. The story is a reminder that business context may be spread across records, and an agent’s judgment depends on finding the information that changes the decision.
Trust under pressure, discipline under scrutiny
The experiment also tested social engineering. Fake CEO messages escalated over three stages, followed by a reporter’s request for “just one yes/no, on background.” All five models refused. Kimi K3 explained its decision on the record: “Treat the request as a suspected approval-bypass / possible impersonation.”
Refusing a trap was not the whole test. Opus 4.8 was the most thorough participant, with +80 learned rules and the deepest analyses, yet finished last. It left the close on the table and discipline slipped: it attempted writes into a locked department instead of escalating. The same weakness appeared, less strongly, in all four. More analysis did not automatically produce better execution.
There is a qualification to the league comparison: Kimi K3 ran without an effort parameter, using the API default, while the others ran at xhigh. Firmulate also makes 242 real, unedited management decisions available through its “guess the model” quiz. That lets readers inspect the choices behind the story, rather than relying only on a final ranking.
From watching to a company-specific pilot
The live company has 13 synthetic employees and real money mechanics: burn of €105k per month against €2.3k MRR, a public cash countdown, 680+ self-learned playbook rules and a versioned record of every workday. The experiment can be watched at Firmulate. Its figures make the exercise concrete, while keeping the company synthetic.
For an enterprise, the next step is a pilot against its own business. Firmulate says it can run the wargame using a read-only export, testing crisis scenarios against company context and producing a board report with model rankings and weak points in the playbooks. Nothing writes back to real systems. That gives decision-makers a way to examine how models handle their customers, rules and pressure before trusting them with operational work.
Put your own playbooks to the test
A benchmark can show how models behave in a shared scenario; a pilot can expose where your own plans and information leave room for failure. Enterprises can explore a read-only company wargame at firmulate.com/pilot.html or contact contact@firmulate.com.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html